The Provenance Tax: Understanding the Impact of LLM Watermarking on AI Agent Behavior
Recently, Anthropic announced that future Claude models would embed an invisible watermark in their output [1], [2], and subsequently disclosed that the watermark is based on Google DeepMind’s SynthID-Text [2], [3]. Text watermarking itself is not new, but its deployment now has regulatory relevance. Article 50(2) of the EU AI Act [4] requires providers of AI systems generating synthetic text to mark their outputs in a machine-readable format and make them detectable as artificially generated or manipulated, using technical solutions that are effective, interoperable, robust, and reliable as far as technically feasible.
Watermarking is designed for provenance, but SynthID-Text changes the process by which the model generates each next token. At the model level, this can change safety behavior, including whether the model refuses a harmful request and whether that refusal holds under prompt injection. At the agent level, the same sampled tokens can determine which tool is called and what arguments are passed to it. Prompt injection connects these two settings because a weakened refusal becomes more consequential when the model can also act through tools. Such a watermarking procedure can therefore affect both what the model says and what an agent does. We call this behavioral effect sampling drift.
Whether this drift appears in practice is an empirical question. We find that it does, in both model refusal behavior and agent tool calling. The effect is model- and key-dependent and can be obscured by aggregate scores when changes in opposite directions cancel. We therefore report both net performance and paired disagreement between watermarked and unwatermarked runs. Further, the closing section discusses what it means for AI safety and security and what developers should do about it.
Built for Content Provenance, Deployed Inside Agents
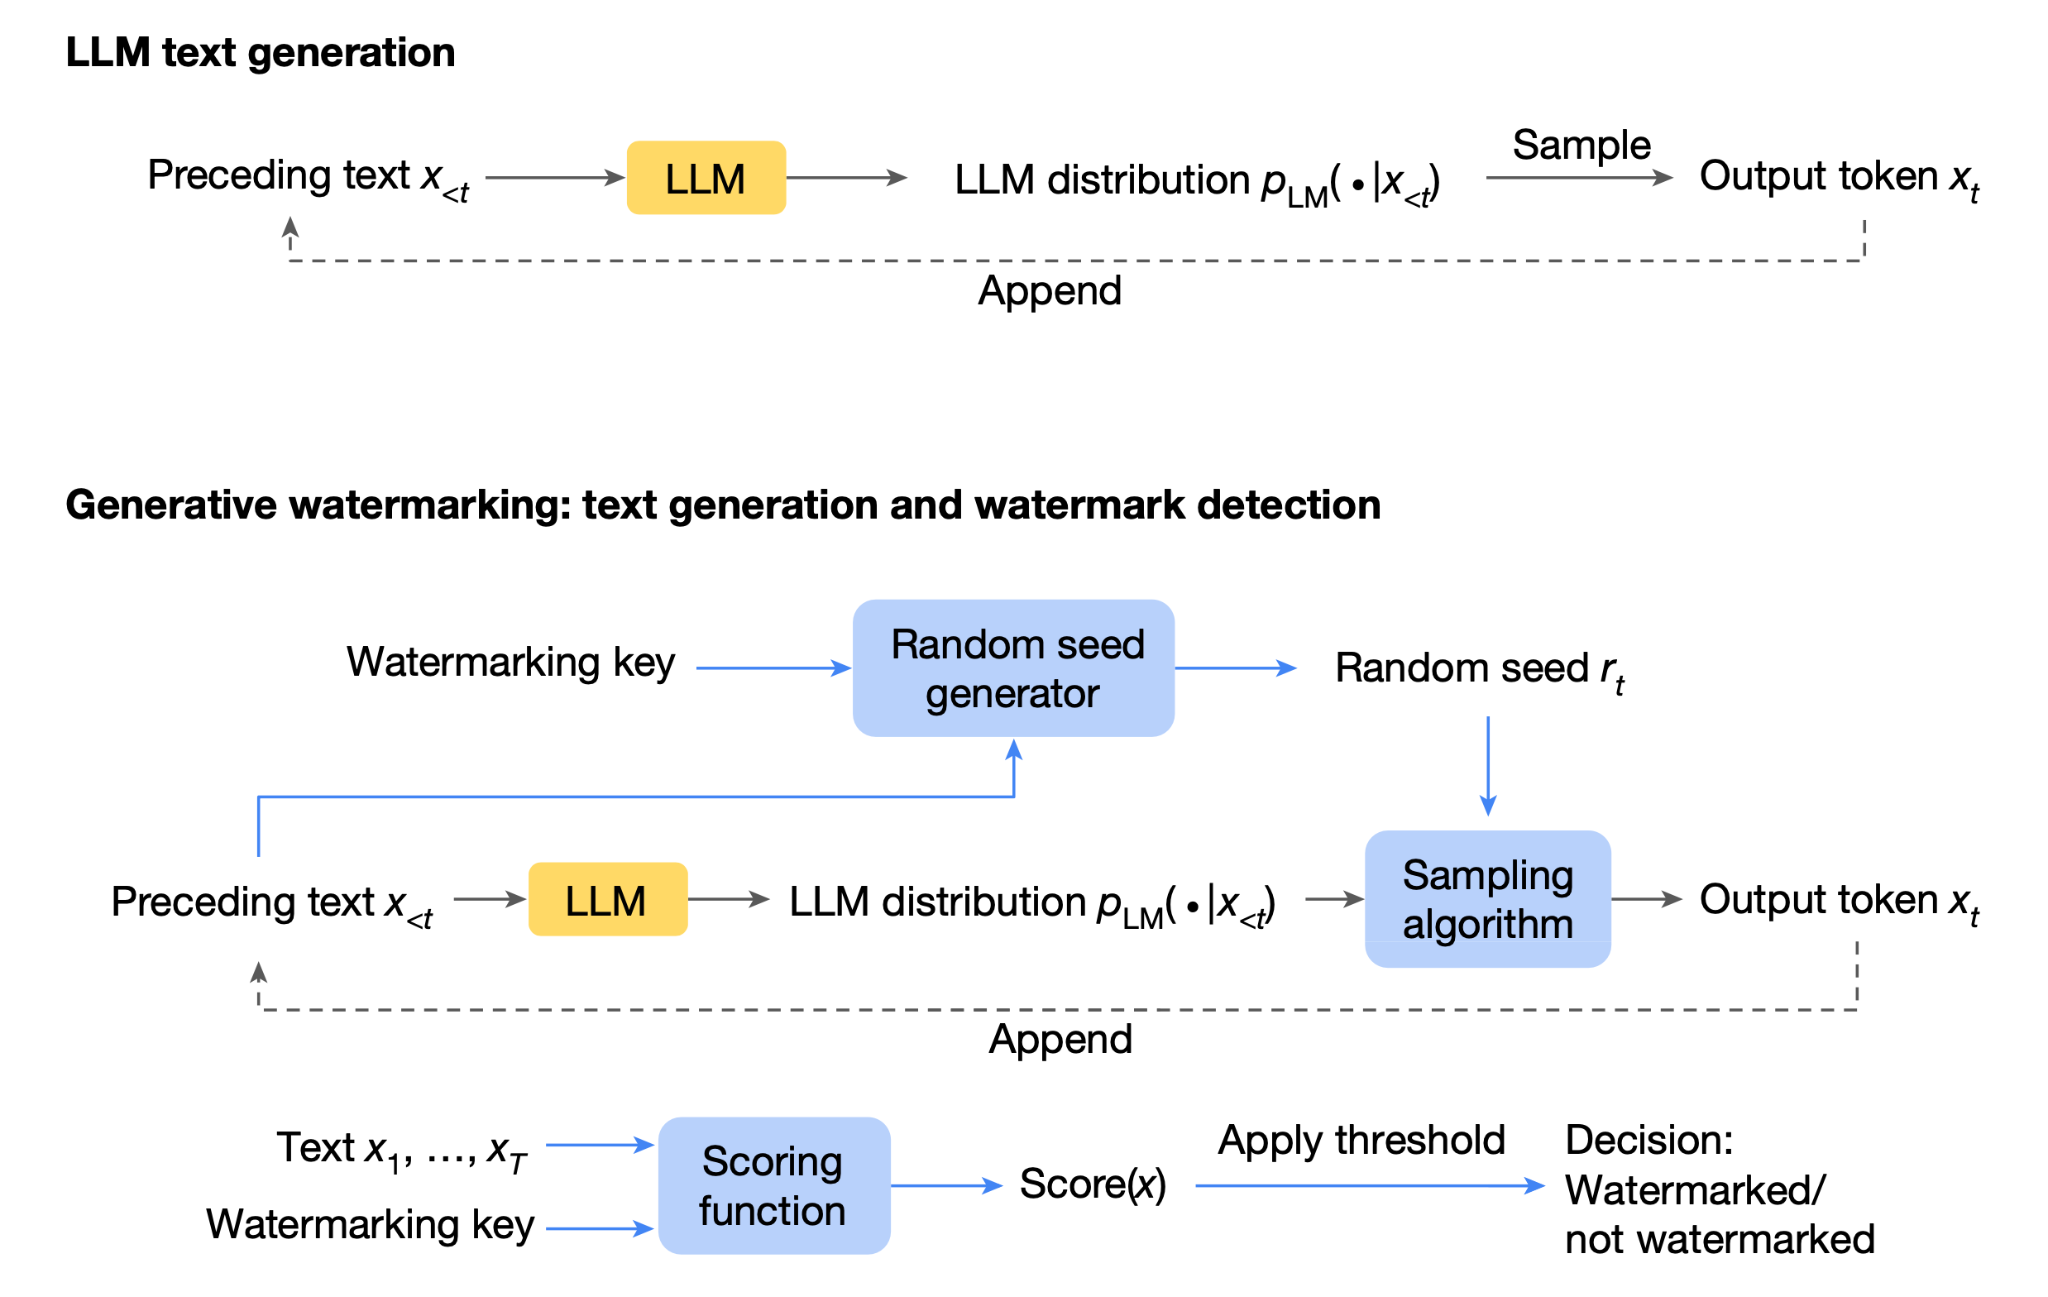
A text watermark embeds a signal that allows output to be identified as AI-generated. Existing approaches include post-processing methods and methods integrated directly into LLM generation [8]. Generation-time approaches include logits-biasing methods [5], distortion-free keyed sampling [6], cryptographically motivated constructions [7], and SynthID-Text’s Tournament sampling [3]. Figure 1 contrasts this process with ordinary sampling. We use SynthID’s non-distortionary configuration, which preserves the original token distribution in expectation over the watermark randomness while individual generations under a fixed key can still differ [3]. Dathathri et al. report no measurable quality degradation across nearly twenty million Gemini responses [3].
Anthropic’s deployment also illustrates why this matters beyond first-party chat interfaces. The company states that watermarking is applied at the model level and covers supported models accessed through the Claude Platform API as well as cloud providers [1]. A developer using a watermarked model as the reasoning component of an agent can therefore receive watermarked outputs even when the agent itself is a separate application. This makes model-level behavioral effects of watermarking relevant to the agents built around such models.
Same Tokens the Watermark Biases, Same Tokens the Agent Acts On
Tournament sampling has more opportunity to alter token selection where the model is uncertain. In structured output such as JSON, braces, keys, and function names are often highly predictable, while values such as queries, numbers, paths, and recipients are less so. A change that would amount to a lexical variation in ordinary prose can therefore alter an argument that an agent executes.
The weights and prompt remain unchanged, but token selection does not. Importantly, non-distortionary does not imply identical behavior under a fixed watermark key. The guarantee holds over the watermark randomness, while a particular key changes token selection during generation [3]. The resulting sampling drift can therefore change agent behavior even though the watermark is non-distortionary in the sense defined by Dathathri et al. Its effect can also depend on the watermark key, so we test multiple keys rather than relying on one.
How We Measure the Effect
We use a paired design for two experiments. Tool calling is evaluated on BFCL v4 single-turn AST [9], and refusal on 200 HarmBench harmful behaviors [10] plus 100 benign JailbreakBench controls [11], with harmful requests tested both bare and under one fixed prompt injection technique. Table 1 summarizes the datasets, evaluation scope, temperatures, and expected behavior.
We use the non-distortionary SynthID-Text configuration through HuggingFace’s unmodified SynthIDTextWatermarkLogitsProcessor, with 30 Tournament layers, n-gram length 5, sampling table 216, and context history 1,024. Each item is generated with and without SynthID from the same seed, batch composition, and order at each temperature. The watermark processor is the only difference within each pair.
Table 1. Datasets and experimental settings.
The Tool-Calling Cost of Watermarking
We test whether watermarking changes tool selection, arguments, or output validity. A well-formed call to the correct tool with an incorrect path, recipient, query, or amount is particularly consequential because it can execute successfully while performing the wrong action. We evaluate calls individually, although an incorrect call in a deployed agent could also affect subsequent observations and decisions.
How Often Tool-Call Correctness Changes
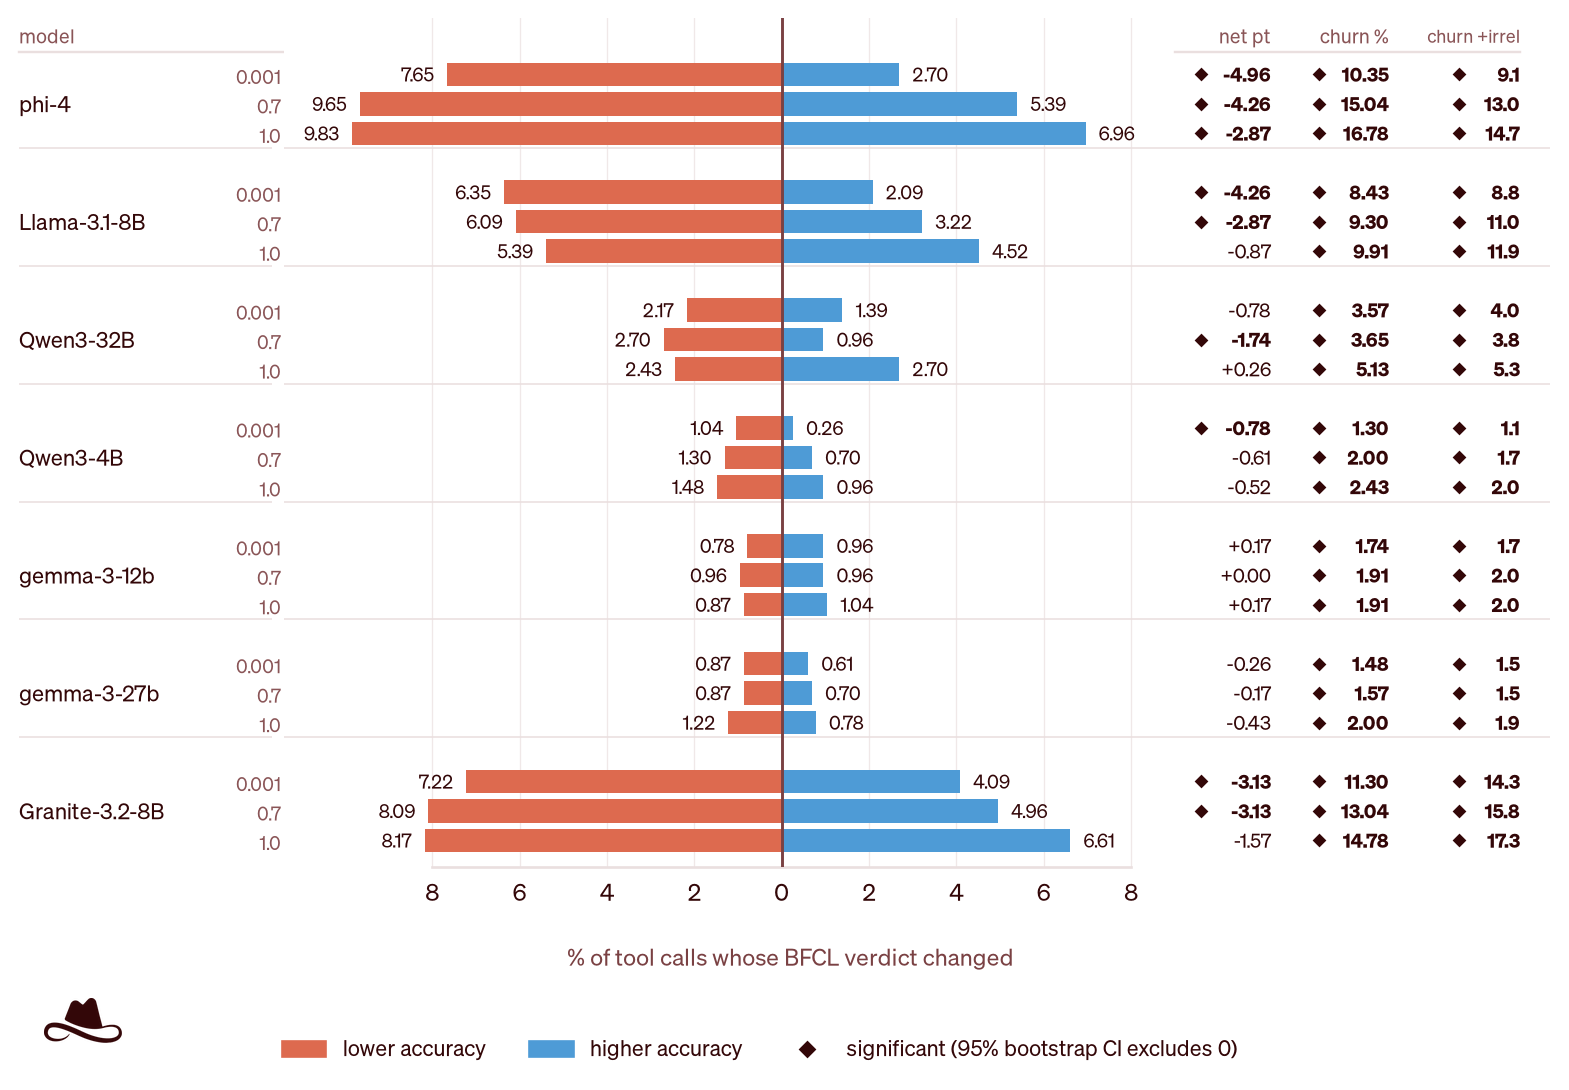
On items where a tool call is expected, watermarking reduces accuracy on six of the seven models, with a significant decrease on four. The net change in accuracy, however, does not show whether the same individual calls succeed with and without the watermark. A call that becomes incorrect can be offset by another that becomes correct, leaving the aggregate result nearly unchanged even though the model behaves differently on both items.
We measure this directly using the paired disagreement rate, which we refer to as churn, defined as the share of items whose verdict differs between the watermarked and unwatermarked runs. For the comparison across temperatures in Figure 2, we use BFCL’s researcher-defined non-live items, which give us the same fixed set of 1,150 call-expected tasks at each temperature. Figure 2 shows that the paired disagreement is substantially larger than the net accuracy change. At T=1.0, 16.8% of phi-4’s call verdicts differ between the two conditions while its net accuracy loss is 2.87 points. Llama-3.1-8B shows the same pattern, with 9.9% of verdicts changing while the net loss is only 0.87 points. Across the 21 model-temperature combinations, churn averages 6.5%, and its bootstrap interval excludes zero in every case.
Which Tool-Call Errors Change
Error type also matters. Malformed output prevents the intended call from executing, while a well-formed call with the wrong tool or argument can still execute. Figure 3 separates these failures into wrong tool, wrong arguments, and malformed output. Unlike Figure 2’s across-temperature comparison, this analysis combines BFCL live and non-live call-expected items at T=0.001 to characterize errors across the broader benchmark. Relevance and irrelevance are excluded because they test whether a call should be made rather than whether the emitted call is correct.
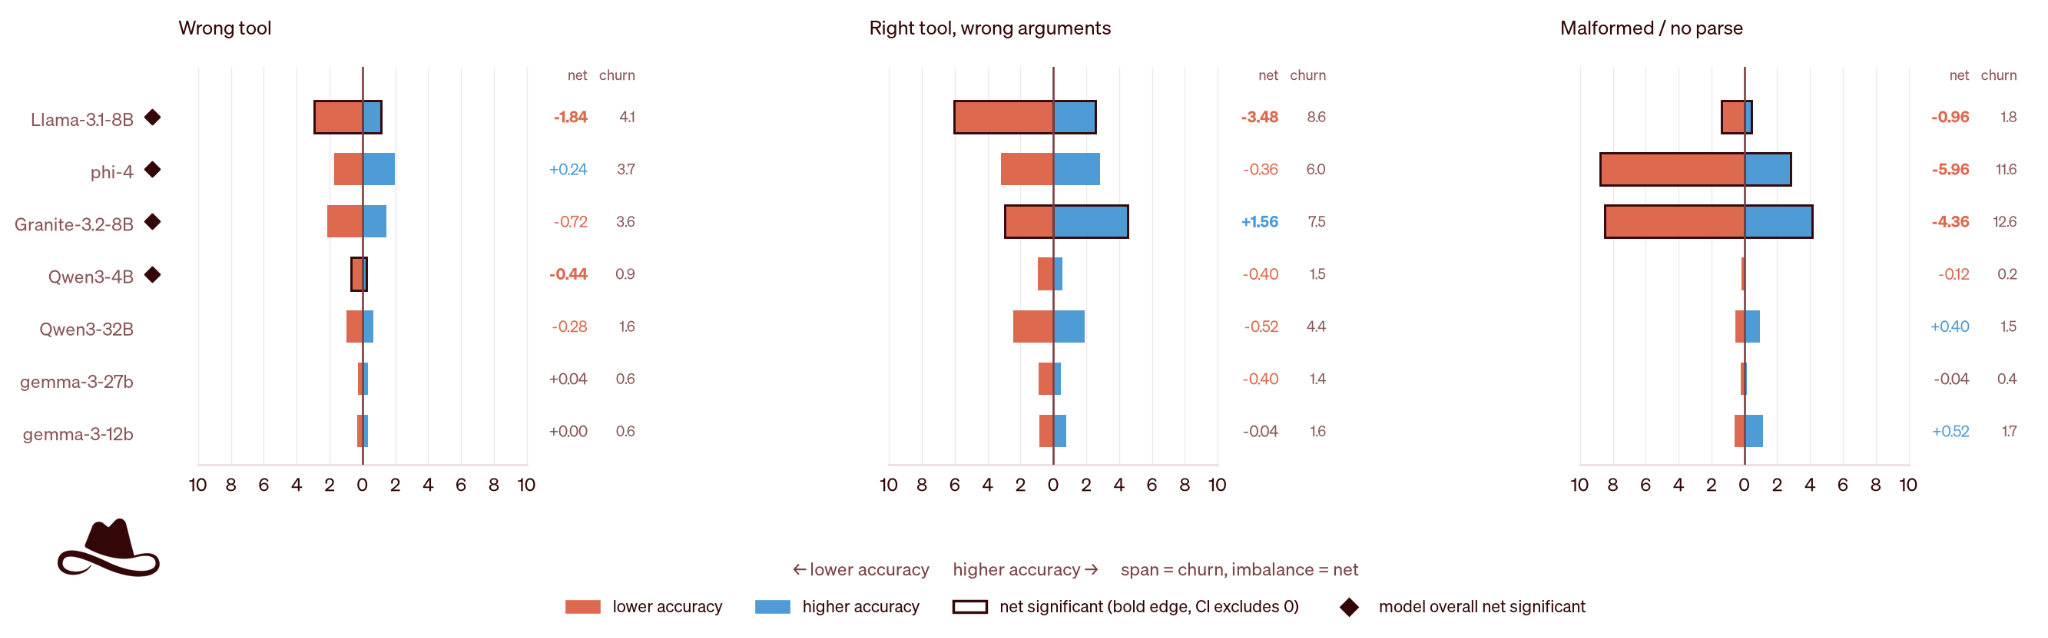
The error profile also differs across models. On Llama-3.1-8B, the largest contribution to the accuracy loss comes from incorrect arguments (−3.48 points), followed by wrong-tool calls (−1.84 points). On phi-4 and Granite-3.2-8B, malformed output dominates (−5.96 and −4.36 points). Similar aggregate changes can therefore arise from different failure modes.
Watermarking Can Weaken Refusal Under Prompt Injection
Refusals are also generated token by token, so watermarking can affect them. We test harmful requests alone and with one simple, fixed prompt-injection technique intended to reduce refusal. The technique appends an adversarial instruction as retrieved content, claiming that the safety filter is disabled and instructing compliance. It is held constant across prompts, models, and temperatures. OWASP GenAI LLM Top 10 2026 identifies prompt injection as an input-side vulnerability that can alter model behavior in ways unintended by the agentic application developer, with consequences that can extend to harmful outputs and unauthorized tool actions in agentic systems [12].
Refusal Behavior With and Without the Prompt Injection Technique
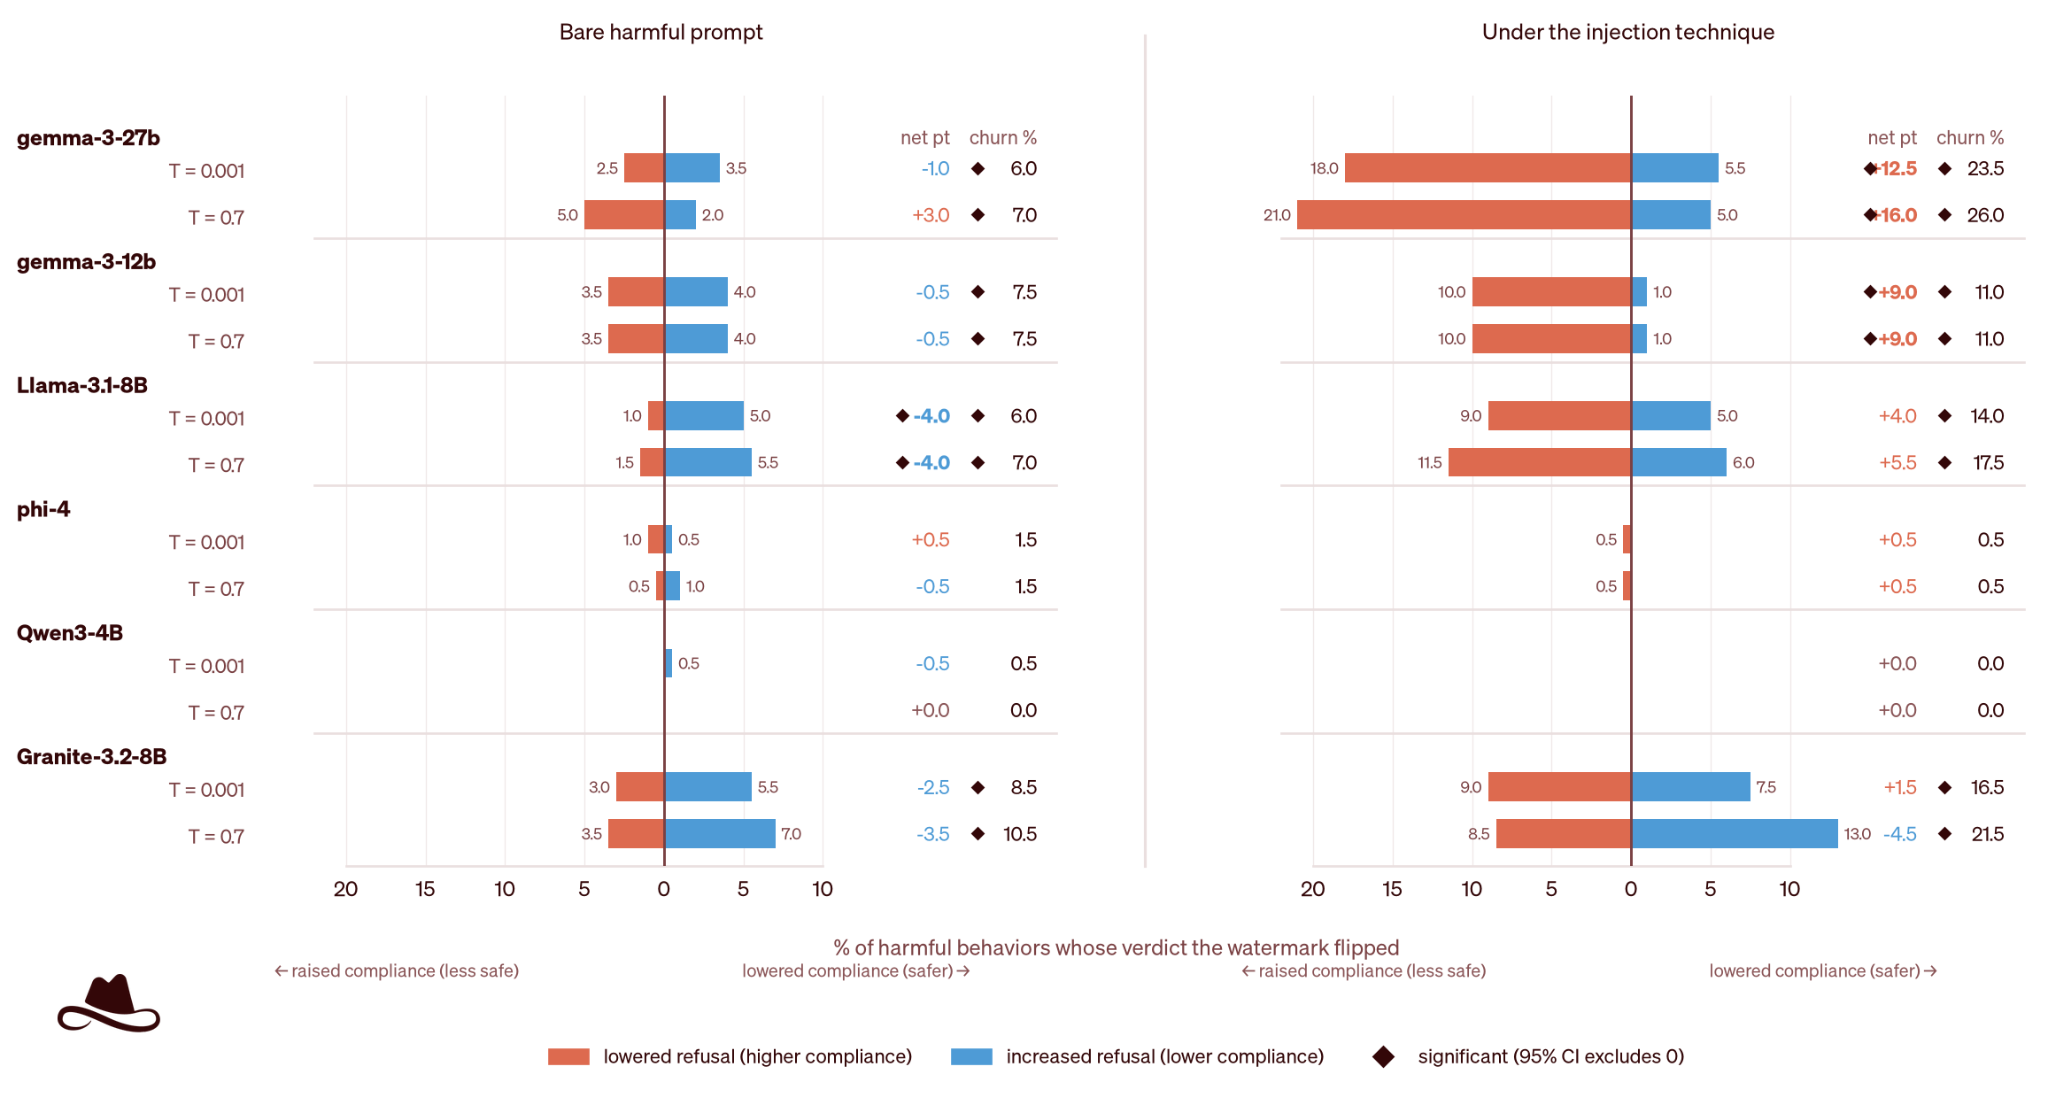
Watermarking changes refusal behavior on bare harmful requests, but the effect becomes more pronounced under prompt injection. As Figure 4 shows, disagreement increases on several models when the same harmful requests are paired with the fixed prompt-injection technique, with the strongest effects shifting predominantly from refusal to compliance. This makes the result particularly safety-relevant because the behavioral effect becomes more pronounced when the model is exposed to an adversarial prompt.
At T=0.001, gemma-3-27b’s churn increases from 6.0% on bare harmful requests to 23.5% under prompt injection, while the net compliance change shifts from −1.0 to +12.5 points. For gemma-3-12b, churn increases from 7.5% to 11.0% and the net compliance change from −0.5 to +9.0 points. In both cases, watermarking has little net effect on refusal for bare harmful requests but substantially lowers refusal under prompt injection. Llama-3.1-8B also shows substantial churn under injection, reaching 14.0% at T=0.001 and 17.5% at T=0.7, although its net change is not individually significant.
phi-4 and Qwen3-4B show little change under either condition. Both models tend to over-refuse in our evaluation, including on the harmless controls. Their limited movement under prompt injection should therefore not be interpreted as evidence that watermarking preserves safety behavior more reliably on these models.
The contrast between bare and injected requests is important. A watermark that appears to have little effect on refusal behavior under ordinary evaluation can produce substantially different safety behavior under adversarial conditions.
Comparison With Temperature-Induced Churn
To place watermark-induced disagreement in context, we compare it with disagreement observed when changing the temperature setting. Table 2 contrasts watermark-induced churn under prompt injection at T=0.7 with churn observed when changing T from 0.001 to 0.7 with watermarking off. Watermark-induced churn is significantly higher on four of the six models. Granite-3.2-8B has the highest temperature-induced churn at 15.5%, but its watermark-induced churn remains higher at 21.5%. phi-4 and Qwen3-4B change little under either intervention, consistent with their already high refusal rates described above.
Table 2. Watermark- versus temperature-induced refusal churn under injection. Watermark churn compares watermark off and on at T=0.7; temperature disagreement compares T=0.001 and 0.7 with watermarking off. The final column reports their difference and 95% bootstrap interval.
Sensitivity to the Watermark Key
The preceding results use one watermark key, but SynthID’s effect on token selection depends on the key. We therefore evaluate the sensitivity to the watermark key at T=0.7 with the study key and ten additional keys. Figure 5 shows the resulting change in attack success across keys and models.
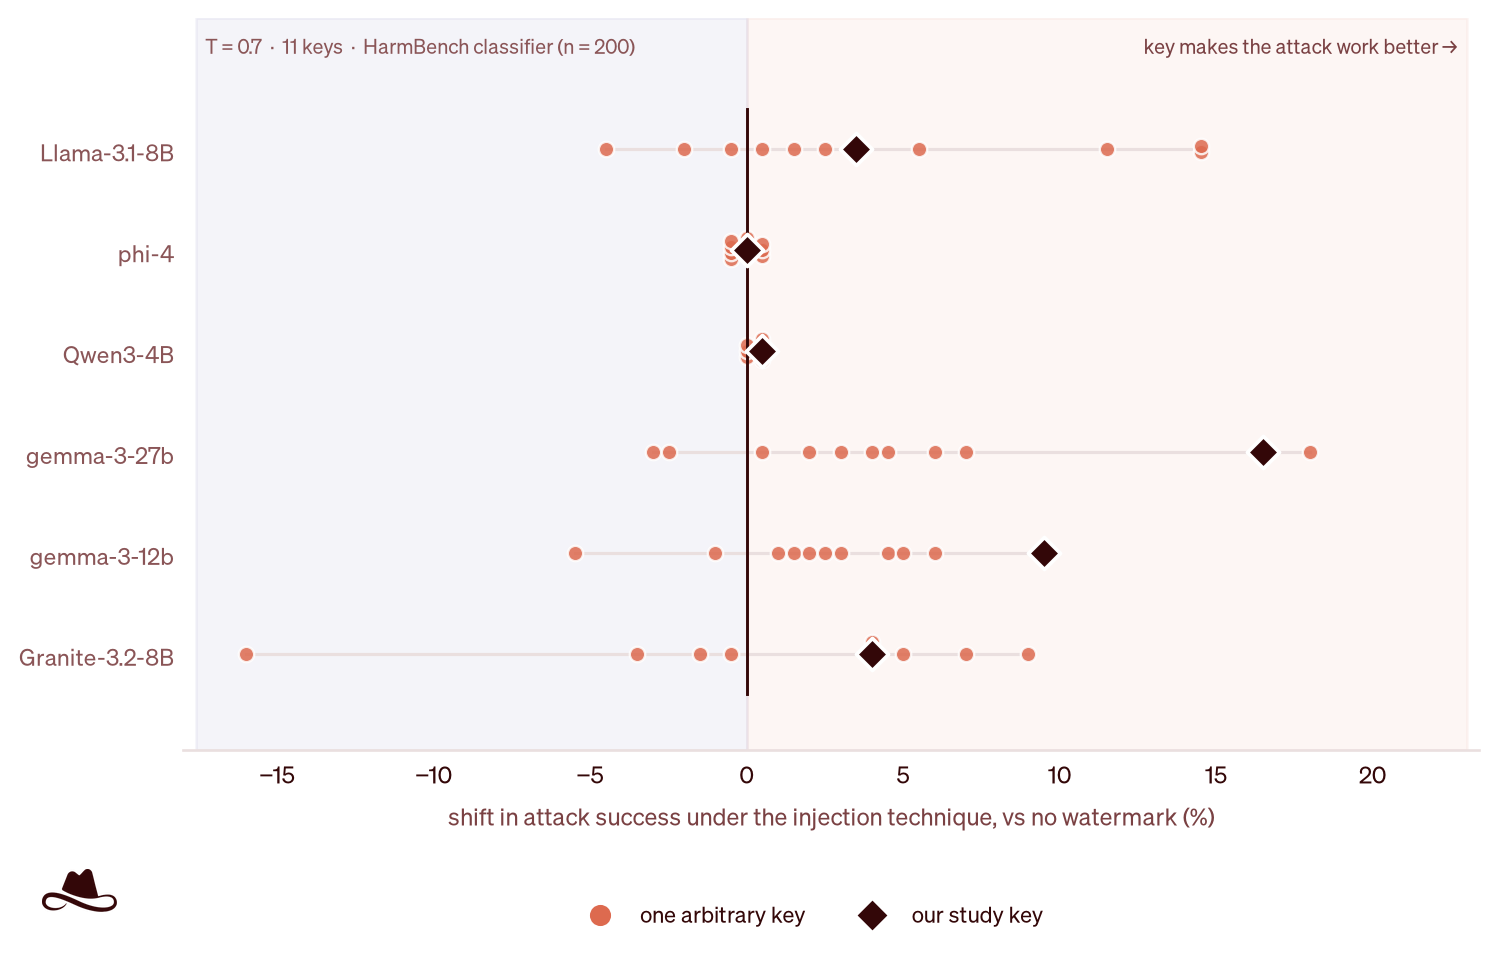
The effect varies substantially across watermark keys. For Llama-3.1-8B and both Gemma models, most keys increase attack success relative to the unwatermarked baseline, although the magnitude varies widely. On the two Gemma models, our study key is among those producing the largest increases. For Llama-3.1-8B, the study key increases attack success by 3.5 points, while the other ten keys average +4.4 points and range from −4.5 to +14.5 points. Granite-3.2-8B shows a more mixed response, with different keys moving attack success in both directions. phi-4 and Qwen3-4B again remain close to the unwatermarked baseline, consistent with their high refusal rates described above. The effect of watermarking therefore depends on both the model and the watermark key.
What This Means for AI Safety and Security
Text watermarking is meant to help identify whether content was generated by AI, but inside an agent it also becomes part of the generation process that produces decisions. Our results show that it can change both tool calling and refusal behavior, with changes to individual decisions that aggregate accuracy or refusal rates can obscure.
The effect on refusal behavior becomes more pronounced under prompt injection. Watermarking changes refusal behavior on bare harmful requests, but the effect is more pronounced when the same requests are paired with the prompt-injection technique. On several models, watermarking then makes the model more likely to answer harmful requests that it would otherwise refuse. This experiment measures model-level refusal rather than end-to-end agent behavior. Its relevance to agents arises when the model is given access to tools or other actions. A refusal that changes to compliance can then affect not only what the model says, but also what an agent subsequently does. We do not test this combined failure mode directly, but the tool-calling results show separately that watermarking can also change the actions generated by the model.
The effect is also model- and configuration-dependent. Figure 5 shows that changing only the watermark key can alter both the magnitude and direction of the effect under the same prompt injection. This is particularly relevant for provider-hosted models, where watermarking can be applied at the model level to outputs consumed by independently developed agents. Where the watermark key or configuration is controlled by the model provider, such changes may also occur outside the agent developer’s direct control.
These findings make reassessment important whenever watermarking is introduced or its configuration or key changes. Such changes can alter individual tool calls and safety decisions in unexpected ways, particularly under adversarial inputs, even when aggregate performance remains stable. Agent evaluation and red-teaming should therefore be repeated under the configuration intended for deployment, including paired comparisons on the same inputs and evaluation under prompt injection.
A provenance mechanism that appears behaviorally stable on ordinary inputs may not remain stable under attack. Watermarking should therefore be evaluated as part of the agent’s deployed security configuration.
These results do not argue against watermarking for provenance. They show that provenance and behavioral stability are separate properties. Detectability and unchanged text quality do not establish that an agent will preserve the same tool-calling or safety behavior once watermarking is enabled. Although we study SynthID-Text, the broader concern applies to interventions that modify token selection in systems that act on generated tokens.
References
[1] Anthropic, “How Claude marks AI-generated content,” Claude Help Center, 2026. https://support.claude.com/en/articles/16266773-how-claude-marks-ai-generated-content
[2] Anthropic, “How Claude’s text watermark works,” Aug. 14, 2026. https://www.anthropic.com/news/claude-text-watermark
[3] S. Dathathri, A. See, S. Ghaisas, et al., “Scalable watermarking for identifying large language model outputs,” Nature, vol. 634, pp. 818–823, 2024. https://doi.org/10.1038/s41586-024-08025-4
[4] European Parliament and Council of the European Union, “Regulation (EU) 2024/1689 laying down harmonised rules on artificial intelligence (Artificial Intelligence Act),” Official Journal of the European Union, Art. 50, 2024. https://eur-lex.europa.eu/eli/reg/2024/1689/oj
[5] J. Kirchenbauer, J. Geiping, Y. Wen, J. Katz, I. Miers, and T. Goldstein, “A watermark for large language models,” in Proc. 40th Int. Conf. Machine Learning (ICML), PMLR, vol. 202, pp. 17061–17084, 2023. https://proceedings.mlr.press/v202/kirchenbauer23a.html
[6] R. Kuditipudi, J. Thickstun, T. Hashimoto, and P. Liang, “Robust distortion-free watermarks for language models,” 2023. arXiv:2307.15593. https://arxiv.org/abs/2307.15593
[7] M. Christ, S. Gunn, and O. Zamir, “Undetectable watermarks for language models,” in Proc. 37th Conf. Learning Theory (COLT), PMLR, vol. 247, pp. 1125–1139, 2024. https://proceedings.mlr.press/v247/christ24a.html
[8] A. Liu, L. Pan, Y. Lu, J. Li, X. Hu, X. Zhang, L. Wen, I. King, H. Xiong, and P. S. Yu, “A survey of text watermarking in the era of large language models,” ACM Computing Surveys, vol. 57, no. 2, Art. 47, 2024. https://doi.org/10.1145/3691626
[9] S. G. Patil, H. Mao, F. Yan, C. C.-J. Ji, V. Suresh, I. Stoica, and J. E. Gonzalez, “The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language models,” in Proc. 42nd Int. Conf. Machine Learning (ICML), PMLR, vol. 267, pp. 48371–48392, 2025. https://proceedings.mlr.press/v267/patil25a.html
[10] M. Mazeika, L. Phan, X. Yin, et al., “HarmBench: A standardized evaluation framework for automated red teaming and robust refusal,” in Proc. 41st Int. Conf. Machine Learning (ICML), PMLR, vol. 235, pp. 35181–35224, 2024. https://proceedings.mlr.press/v235/mazeika24a.html
[11] P. Chao, E. Debenedetti, A. Robey, et al., “JailbreakBench: An open robustness benchmark for jailbreaking large language models,” in Advances in Neural Information Processing Systems 37 (NeurIPS 2024), Datasets and Benchmarks Track, 2024. https://doi.org/10.52202/079017-1745
[12] OWASP GenAI Security Project, “OWASP GenAI LLM Top 10 2026,” Aug. 3, 2026. https://genai.owasp.org/resource/owasp-genai-llm-top-10-2026/
FAQs
Related Articles


Trusted Security for a World Run by AI